Курсовая работа (т): Лингвистические и стилистические особенности текстов научного стиля английского языка
• использование страдательного залога в качестве безличных конструкций [Поспелова 2012: 12]:
It is possible for a single track to exist that passes within given thresholds of each observation.− Возможно существование единичной трассы, проходящей в пределах заданных пороговых величин для каждого наблюдения.
Номинальность.
Это означает, что в современной письменной речи научного стиля развилась тенденция к явному преобладанию существительных и выражению действия преимущественно не через глагол, а через отглагольное существительное с десемантизированным глаголом. Это повышает статус объективности изложения, поскольку увеличивает уровень абстрактности [Алексеева 2001: 168]:
First, maintaining and querying the parameter space representation can be expensive in terms of both computation and memory.− Во-первых, хранение и использование параметрического представления может потребовать больших вычислительных затрат и перегрузить память ЭВМ.
Информационная насыщенность.
С функциональной точки зрения письменная речь является необычайно информационной по цели высказывания, потому что обычно создается в контролируемых ситуациях, когда есть время на обдумывание и возможно что-то переписать по-другому. Любой научный текст отличается богатым арсеналом вспомогательных знаковых систем (включая схемы и чертежи в техническом тексте) [Алексеева 2001: 168].
Сжатость.
При всей информационной насыщенности для текста, написанного в научном стиле, характерна сжатость изложения материала, так называемая компрессия. Она может быть достигнута за счет определенных синтаксических конструкций:
словосочетаний имен существительных, например:
• parameter space− параметрическое пространство;
• track initiation− завязка трасс;
словосочетаний имен существительных с атрибутивными прилагательными, например:
• an exact algorithm− точный алгоритм;
• a simple form− простая форма;
замены придаточных предложений причастными или инфинитивными конструкциями, например:
• a high branching factor causing a significant computational load− высокий коэффициент ветвления, вызывающий значительную вычислительную нагрузку.
• intersections to spread out over several bins and be missed− пересечения, распространяющиеся на несколько клеток и вызывающие ошибки.
фраз с предлогами, например:linear track model
cannot account for changes in velocity− линейная модель трассы не может
учитывать изменение скорости [Поспелова 2012: 13].
1.3 Разновидности текстов научного стиля
Основными источниками научной информации являются многочисленные периодические издания, публикуемые в англоязычных странах почти по всем отраслям науки и научным направлениям, а также издания, обобщающие опыт работы специалистов различных научных обществ. К такой периодике относятся прежде всего научные журналы, доклады научно-исследовательских учреждений, обзорные статьи, бюллетени и т. д. [Айзенкоп 2003:55].
Существует несколько разновидностей научного
стиля.
1. Собственно научный (монография, диссертация, научная статья, доклад).
. Научно-популярный (лекция, статья, очерк). Данный подстиль научного стиля реализует дополнительную функцию - «перевод» специальной научной информации на язык неспециального знания, тем самым происходит популяризация научных знаний для широкой аудитории [Кожина 2006:236].
. Учебно-научный (учебник, методическое пособие, лекция, конспект).
. Научно-деловой (техническая документация, сообщения об испытаниях, инструкции для предприятия).
. Научно-информативный (патентное описание, реферат, аннотация, тезисы).
. Научно-справочный (словарь, энциклопедия, справочник, каталог).
Научный стиль реализуется в крупных и малых жанрах. К первым относятся: монография (индивидуальная и коллективная), диссертация, энциклопедия, словарь, справочник, учебник, учебное пособие. Ко вторым - статья в периодическом или непериодическом издании, реферат, тезисы, аннотация и др. Малые жанры выделяются не только по количественному признаку. Обычно они не обладают отдельностью: статьи, рефераты, тезисы помещаются в журналах и сборниках. В крупных жанрах, например, в учебнике, соседние части подчинены целому, даже при разном авторстве, т.е. связаны как логико-смысловой, так и внешней линейной связью.
Известны различные классификации жанров научного стиля. В зависимости от степени обобщения научных сведений выделяются первичные научные произведения и вторичные. Целевое назначение первичных жанров научного стиля состоит в изложении первичных научных сведений, получаемых в процессе исследований. В отличие от них, вторичные научные произведения информируют только о конечных результатах исследований, полученных в процессе аналитико-синтетической переработки первичных научных текстов.
Можно выделить следующие первичные жанры научной прозы: монография, справочник, журнальная статья, рецензия, учебник, лекция, доклад, диссертация, научный отчёт. К вторичным текстам, то есть к текстам, составленным на основе уже имеющихся, относятся: реферат, автореферат, конспект, тезисы, аннотация. При подготовке вторичных текстов происходит свёртывание информации в целях сокращения объёма текста [Кожина 2006: 57-58].
Следует дать характеристику некоторым из названных жанров научного стиля.
Монография <#"808551.files/image001.gif">
Figure 1: The linkage problem is to find one point at each time step such that the points fit the model for a candidate track. Points from each of the five different time steps are shown as different shapes (square → circle → triangle → diamond → plus). Two linear linkages are shown (B) and a third is left as an exercise for the reader.
is an important problem in such
fields as target tracking and computer vision, but our primary motivating example
in this paper is the asteroid linkage problem. Here we wish to determine which
observed objects correspond to the same true underlying object from a series of
visual observations of the night sky. These linkages can then be used to
determine tentative orbits, attribute the observations to a known orbit, and
assess the potential risk of an asteroid. The use of new observation techniques
and equipment has increased the scope and accuracy of this problem, providing
the potential to track hundreds of thousands of asteroids. The next generation
of sky surveys, such as PanSTARRS or LSST, are designed to provide vast amounts
of observational data that can be used to search for potentially hazardous
asteroids. Further, these surveys have the potential to allow us to detect and
track fainter objects. However, these improvements greatly increase the
combinatorics of the problem reinforcing the need for tractable algorithms.we
introduce a new methodology for track initiation. Instead of treating track
initiation as a sequential decision problem, we exhaustively consider all
possible linkages. Thus we provide an exact algorithm for linkages. We then
introduce a multiple tree algorithm for tractably finding the linkages. We
compare this approach to an adapted version of multiple hypothesis tracking
using spatial data structures and show how the use of multiple trees can
provide a significant benefit.Definitiontrack initiation problem consists of
taking sets of observations from different time steps and linking together
those observations that fit a desired model without initial estimates of the
track parameters. Figure 2 shows a simple one dimensional example with five
time steps and a linear model. The sets of linked observations are shown as
open circles with their linear models as dashed lines.
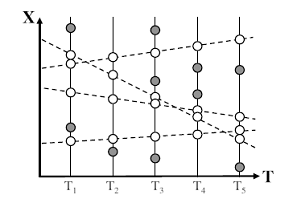
Figure 2: A set of one dimensional observations linked together by linear tracks. The white circles are the observations that correspond to the linear tracks (dashed lines).
the linkage problem can be phrased
as a filtering problem. At each time step k we observe Nk points from both the
underlying set of tracks and noise. Given a set of observations at K distinct
time steps, we want to return all tuples of observations such that:
1. the tuple contains exactly one observation per time step, and
2. it is possible for a single track to exist that passes within given
thresholds of each observation.we wish to filter the ∏Kk=1 Nk possible
tuples down to just those tuples that could be feasible tracks.observations
consist of real-valued coordinates in D dimensional space, with xi indicating
the ith observation. These coordinates are the dependent variables of the
track. We use ti to indicate the independent variable of the ith observation.
Although in many of the applications below ti will correspond to the time of
the observation, it can be used to represent any independent variable.second
condition specifies a constraint on the observations’ fit to the underlying
model. A tuple of observations (xI1 , ··· , xIK) is valid only if there exists
a track g such that:
δL[d] ≤ xIi[d]
− g(tIi)[d] ≤ δH[d]
∀d, i (1)
Equation 1 states that a track g is
feasible for a tuple of observations if it falls within some bounds [g(tIi)[d]+
δL[d],
g(tIi)[d]+ δH[d]] of each
observation xIi in each dimension d. The thresholds δL
and δH
provide upper lower bounds on the fit. Figure 3 shows an example of a feasible
triplet using linear tracks and one feasible track for these points. The track
is allowed to pass anywhere within the error bars around each point.
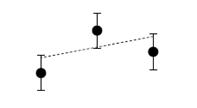
Figure 3: Three points that are compatible for linear tracks.
above definition of feasibility is
compatible with a range of statistical noise models. For example, we can define
an arbitrary observation noise model for the points on a track and set the
thresholds in each dimension to be the 95% confidence interval for the noise in
this dimension. Figure 4 shows an example of this. Further, we can vary δL
and δH
to account for systematic or time varying errors.
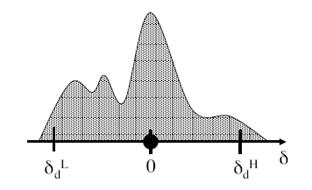
Figure 4: An arbitrary probability distribution and the resulting bounds. The circle denotes the observed location and the upper and lower bars indicate the acceptable locations for the track.
contrast to the flexibility for noise models, it should be noted that the above criteria does not allow for a concept known as process noise. This means that we assume the track always follows the model. For example, a linear track model cannot account for changes in velocity. This is briefly discussed in Section 8.discussion below focuses on two major types of tracks: linear and quadratic. The quadratic track is simply a quadric function of time:
(t) = a · t2 + b · t+ c (2)
can be used to describe physical motions of objects undergoing constant acceleration. The linear track is a linear function of time:
(t) = b · t + c (3)
can be used to describe the physical
motion of objects traveling at a constant velocity. In addition, the linear
model can be used for such queries as finding lines or edges described by the
observations. While much of our discussion and techniques presented below will
also apply to other track models, we restrict the discussion to the linear and
quadratic models to keep the discussion simple and consistent.Workare a variety
of different approaches to the problem of track initiation. Below we briefly
discuss some of the more common ones. These approaches differ from our own in
several important ways. First, we are asking a different type of query.
Specifically, we are asking for all sets of observations that could feasibly
belong to a path. Second, we provide an exact algorithm for answering this
query.Track Initiationcommon approach to track initiation is sequential track
initiation [Blackman and Popoli, 1999]. The unassociated points are treated as
new tracks and projected to the later time steps where they are associated with
other points to form longer tracks. There are many variations to this type of
approach. One common and often successful variation is a very simple form of
multiple hypothesis tracking. When a tentative track matches multiple
observations at a given time step, multiple hypothesizes (tentative tracks) are
formed and the decision is delayed to a later time step. This process is
illustrated in Figure 5. The single point matches three other points at the
second time step. These points are used to create three hypothesized tracks.
This process continues to the third and fourth time step with “bad” hypotheses
being pruned away.order to reduce the number of candidate neighbors examined gating
is used. As shown in Figure 6, neighbors are first filtered by whether they
fall within a window or gate around the track’s predicted position. This
approach has also been used in conjunction with kd-tree structures to quickly
retrieve the candidate observations near the predicted position of a track
[Uhlmann, 1992, Uhlmann, 2001 ].are several potential disadvantages of this
type of approach that arise from the sequential nature of the search itself. It
does not use evidence from later time steps to aid early decisions. Early “good
pairs” may be easily pruned using a lack of further points along the track.
Further, this approach has the potential of being thrown off by noise early in
the track. Multiple hypothesis tracking attempts to mitigate this problem by
allowing multiple tentative tracks, but introduces another problem, the
possibility of a high branching factor causing a significant computational
load.
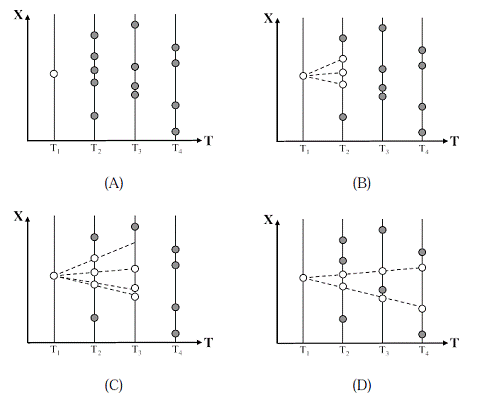
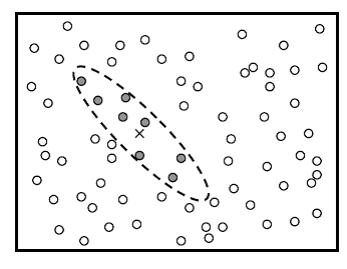
Figure 6: Gating can be used to ignore points that could not be part of the current track. The predicted position of the track is shown as an X and the points that fall within the gate are shaded.
should be noted that sequential
track initiation has the advantage that it can be applied to multiple tracks
simultaneously. This gives this approach the ability to discount observations
that are “obviously” members of other tracks.
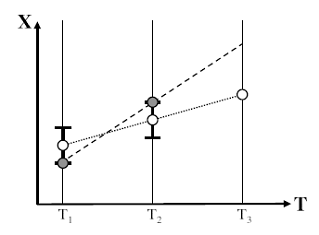
Figure 7: Early noise in a track can significantly throw-off predicted positions. The true points are shown as open circles and the observed points are shown as shaded circles.
Space Methodsapproach to the problem
of track initiation is to search for tracks in parameter space. One popular
algorithm is the Hough transform [Hough, 1959]. The idea behind these approaches
is that for many simple models, individual observations correspond to simple
regions or curves in parameter space. An example with a linear model is shown
in Figure 8. The points are shown in Figure 8.A and their corresponding lines
in parameter space in Figure 8.B. If a series of observations lie along a line,
then their lines in parameter space will intersect at a common point. The Hough
transform looks for lines by using grid-based counts of the number of lines
that go through a particular region of parameter space (Figure 8.C and 8.D).are
several major downsides to the parameter space approach. First, maintaining and
querying the parameter space representation can be expensive in terms of both
computation and memory. There are many possible intersections to check and
storing occurrences in a grid structure may require significant amounts of
space. Secondly, the level of discretization of parameter space can drastically
affect the accuracy of the algorithm.
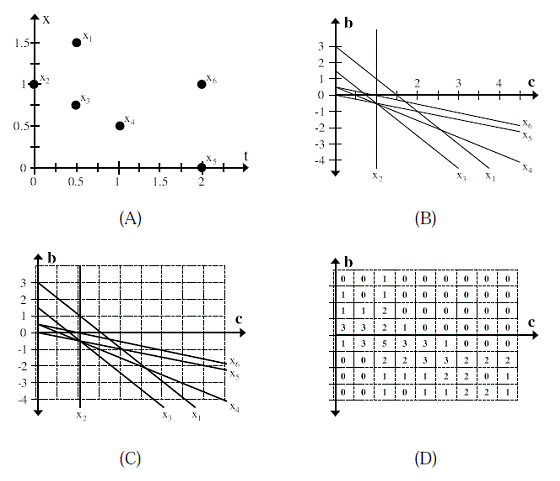
Figure 8.
the grid is too tight then a small amount of noise can cause intersections to spread out over several bins and be missed. If the grid is too loose then coincidental occurrences can accumulate and cause false alarms. Although the false alarms can be filtered out in post-processing, this step further increases the computational cost.